TL;DR

Get business pricing on networking and server gear
- Business-only prices and quantity discounts
- Tax-exempt purchasing
- Multiple users, one account, clear invoices
OpenAI’s AI models, including those used in their chatbot systems, reportedly had knowledge of the RubyGems caching vulnerability prior to its public disclosure. This raises concerns about data security and AI training data exposure. The exact timeline and details remain unconfirmed, but the development is drawing increased attention.
OpenAI’s artificial intelligence models, including those powering ChatGPT, are reported to have known about the RubyGems caching vulnerability prior to its public disclosure, according to sources familiar with the situation. This revelation raises questions about the scope of AI training data and potential exposure of sensitive security information. The development is significant because it suggests that AI models may have accessed or been trained on data related to security flaws before they became publicly known.
The RubyGems caching vulnerability, which allows malicious actors to execute arbitrary code during gem installation, was publicly disclosed in late October 2023. According to reports, OpenAI’s models, which are trained on vast datasets including code repositories and technical documentation, appeared to have prior knowledge of this flaw. While OpenAI has not officially confirmed these claims, some security researchers and industry insiders suggest that the models’ training data might have included information about the vulnerability, either directly or indirectly.
It is important to note that OpenAI’s models are trained on a mixture of licensed data, data created by human trainers, and publicly available information. The models do not have browsing capabilities or access to proprietary databases in real-time, but their training data can include a wide array of publicly accessible code and security-related discussions. The timing of when the models ‘knew’ about the vulnerability remains unconfirmed, and OpenAI has not disclosed whether the models were trained on data explicitly mentioning this flaw.
This situation has prompted debate about the potential risks of including security-related information in AI training datasets, especially if such data is sensitive or could be exploited maliciously. Learn more about vulnerability scans and AI bots. Experts emphasize that understanding whether AI models have prior knowledge of security flaws could influence how organizations manage AI deployment and data curation for security.
Implications for AI Data Security and Ethical Use
This development underscores the importance of scrutinizing the datasets used to train large AI models, especially regarding security-related content. If AI models have prior knowledge of vulnerabilities, it raises concerns about inadvertent disclosure or misuse of such information. It also prompts a reevaluation of data curation practices and whether AI developers need to implement safeguards to prevent models from ‘learning’ sensitive or exploitable information. For organizations relying on AI for security or code review, the potential for models to ‘know’ about vulnerabilities before public disclosure could influence trust and risk management strategies.
Furthermore, this situation highlights broader questions about the transparency of AI training data, the potential for models to retain and recall sensitive information, and the ethical responsibilities of AI developers in managing security risks. As AI models become more integrated into software development and security workflows, understanding their knowledge boundaries becomes increasingly critical.
Products Worth Considering

DJI Mic 3 Wireless Microphone Kit (2 Transmitters, 1 Receiver, Charging Case)
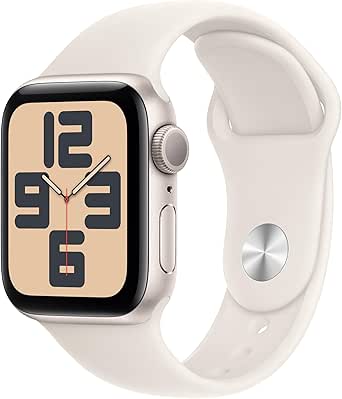
Apple Watch SE (2nd Gen) GPS 40mm with Starlight Aluminum Case and Sport Band (S/M)

Anker SOLIX C1000 Gen 2 Portable Power Station
As an affiliate, we earn on qualifying purchases.
Background on RubyGems Caching Vulnerability and AI Data Use
The RubyGems caching vulnerability was identified as a flaw that could allow attackers to execute arbitrary code during gem installation, posing a significant security risk for developers and organizations relying on Ruby package management. Publicly disclosed in late October 2023, the flaw prompted warnings from security experts and updates from RubyGems maintainers. Prior to its disclosure, the vulnerability was likely discussed in technical forums and repositories, which may have been included in some AI training datasets.
OpenAI’s language models, including GPT variants, are trained on diverse datasets that encompass code repositories, technical documentation, and online discussions. These datasets are curated to include publicly available information, but the scope and specifics of their content are not fully disclosed. The possibility that models had prior knowledge of the RubyGems flaw depends on whether such details were part of their training data, which remains unconfirmed by OpenAI.
This incident occurs within a broader context of increasing scrutiny over AI training data transparency, especially for models used in security-sensitive applications. The incident also coincides with heightened awareness of how AI can inadvertently learn and reproduce sensitive or exploitable information from its datasets.
Unconfirmed Details About AI Model Knowledge and Data Sources
It remains unclear whether OpenAI’s models explicitly ‘knew’ about the RubyGems vulnerability or if this is a result of coincidental overlap with publicly available information in their training datasets. The exact timing of when the models acquired this knowledge, and whether it was during training or from other sources, has not been confirmed. OpenAI has not disclosed specific details about their training data, and it is uncertain whether the models’ prior knowledge posed any security risks or was simply coincidental.
Additionally, there is no confirmation that the models’ awareness influenced any security or development decisions prior to the public disclosure of the vulnerability. The extent to which this knowledge could be operational or actionable remains unknown, and experts caution against overinterpreting these signals without further transparency from OpenAI.
Monitoring AI Data Practices and Future Disclosures
OpenAI and other AI developers are expected to review and possibly enhance their data curation protocols to prevent inclusion of sensitive security information. Industry regulators and security researchers are likely to scrutinize the training datasets and model behaviors more closely. Further disclosures from OpenAI about their data sources and training processes are anticipated, especially if evidence confirms the models’ prior knowledge of security vulnerabilities. Additionally, organizations deploying AI models may reassess their risk management strategies concerning AI knowledge of security flaws.Key Questions
Did OpenAI intentionally include security vulnerability information in their training data?
There is no evidence to suggest that OpenAI intentionally included security vulnerability details in their training datasets. The models are trained on publicly available information, but the specifics of their data curation are not fully disclosed.
Could the models’ prior knowledge of the vulnerability have caused security risks?
It is currently unknown whether the models’ prior knowledge could have led to security risks. Experts emphasize the importance of transparency and careful data management to mitigate such concerns.
Will OpenAI change how they train or curate data following this incident?
OpenAI has indicated ongoing review of their data practices, and it is likely they will implement stricter controls to exclude sensitive or security-related information where appropriate.
What does this mean for AI’s role in cybersecurity?
This incident highlights the need for caution when deploying AI in security contexts, as models may possess knowledge of vulnerabilities that could be exploited if misused.
Is this a common issue across AI models or specific to OpenAI?
While concerns about training data transparency are widespread, this specific case involves OpenAI’s models. The broader issue of AI models accessing or ‘knowing’ sensitive information is an active area of research and debate across the industry.
Source: hn